Predicting workspace price tiers
Gradient boosting, out-of-fold target encoding, and a macro-F1-tuned blend
Section 2 of the ML Projects Course
The task
- Each row is a bookable workspace listing.
- Predict
price_tier, an ordered class from 1 to 4.
- 279,746 training rows, 114,538 test rows, 58 features.
- Metric: macro F1.
Macro F1 weights every tier equally
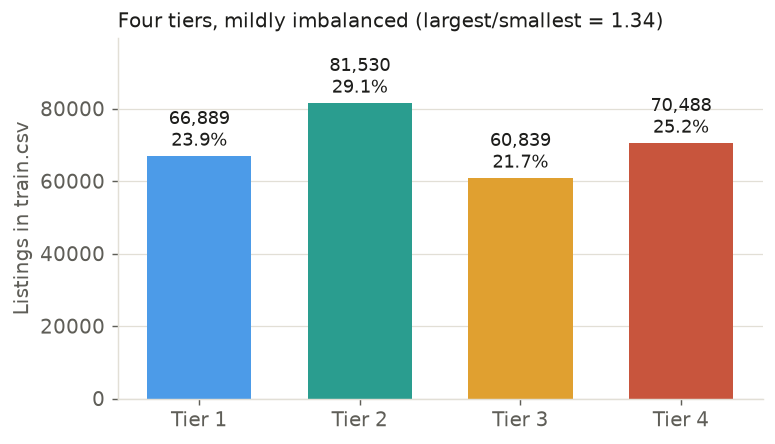
- Tiers: 66,889 / 81,530 / 60,839 / 70,488.
- Largest class is 1.34 times the smallest.
- A weak tier can't hide behind a strong one.
Explore: signal and structure
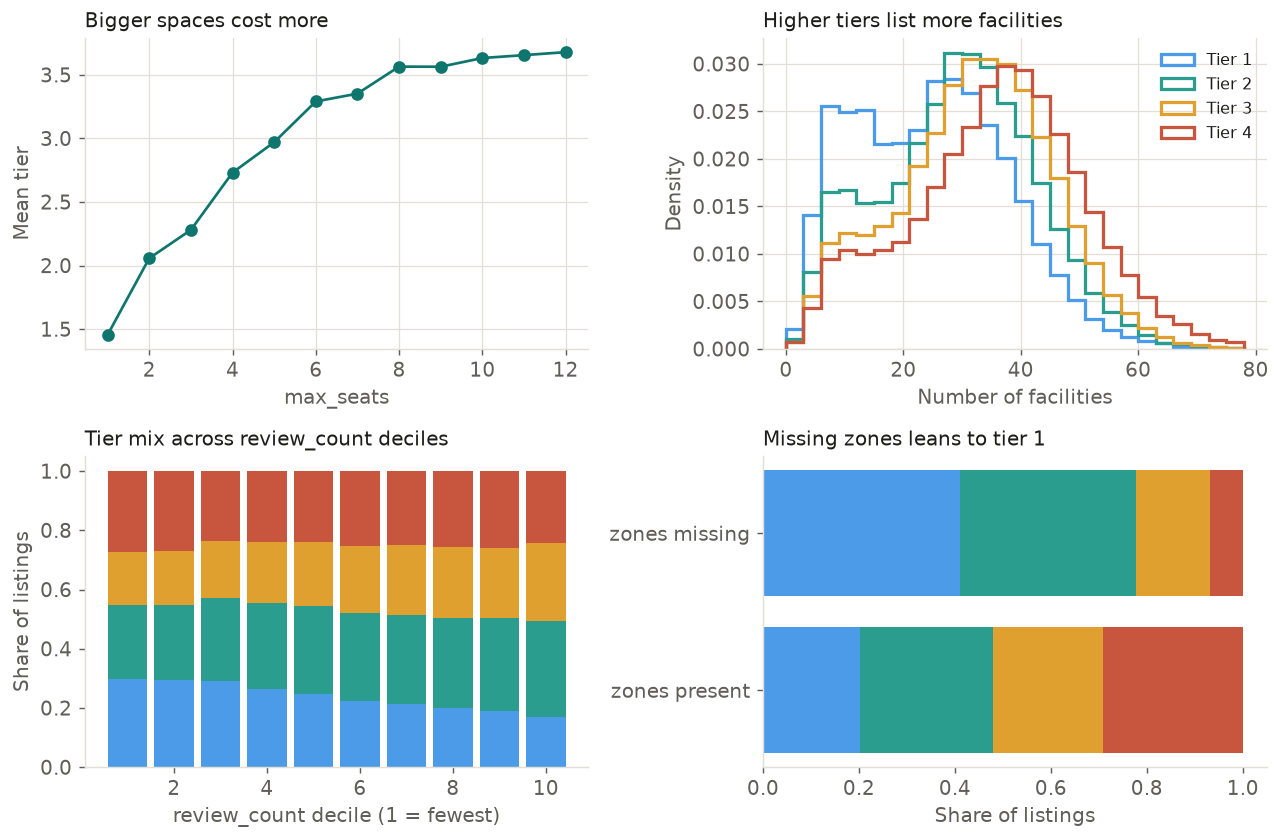
Missing values carry meaning
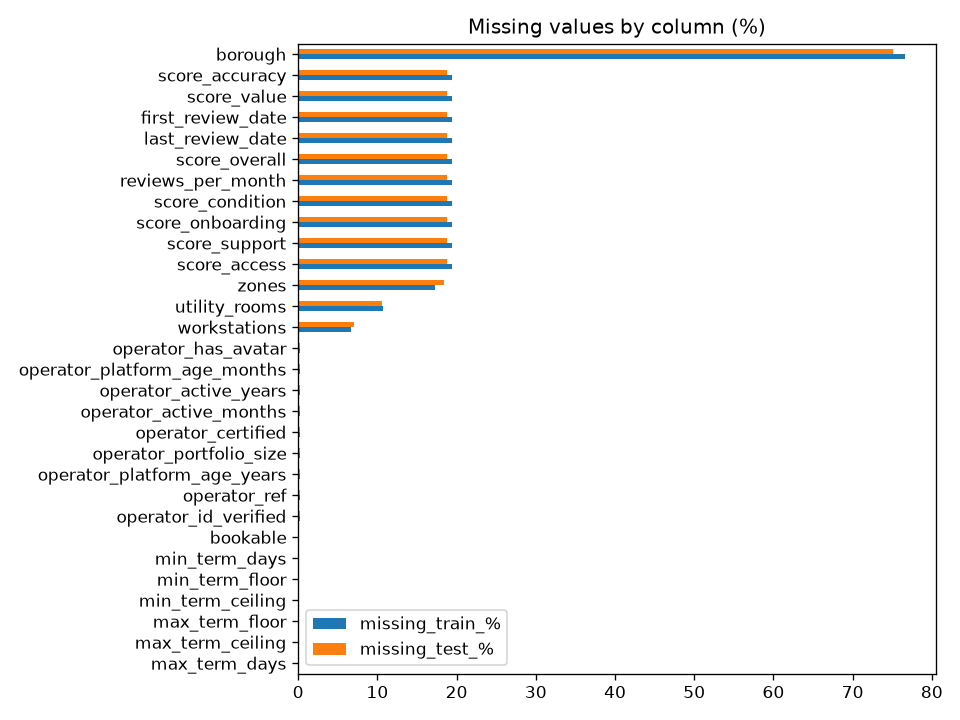
- Borough: structurally missing in 11 of 16 metros.
- Reviews: missing when there are no reviews.
- Median fill plus an indicator keeps the signal.
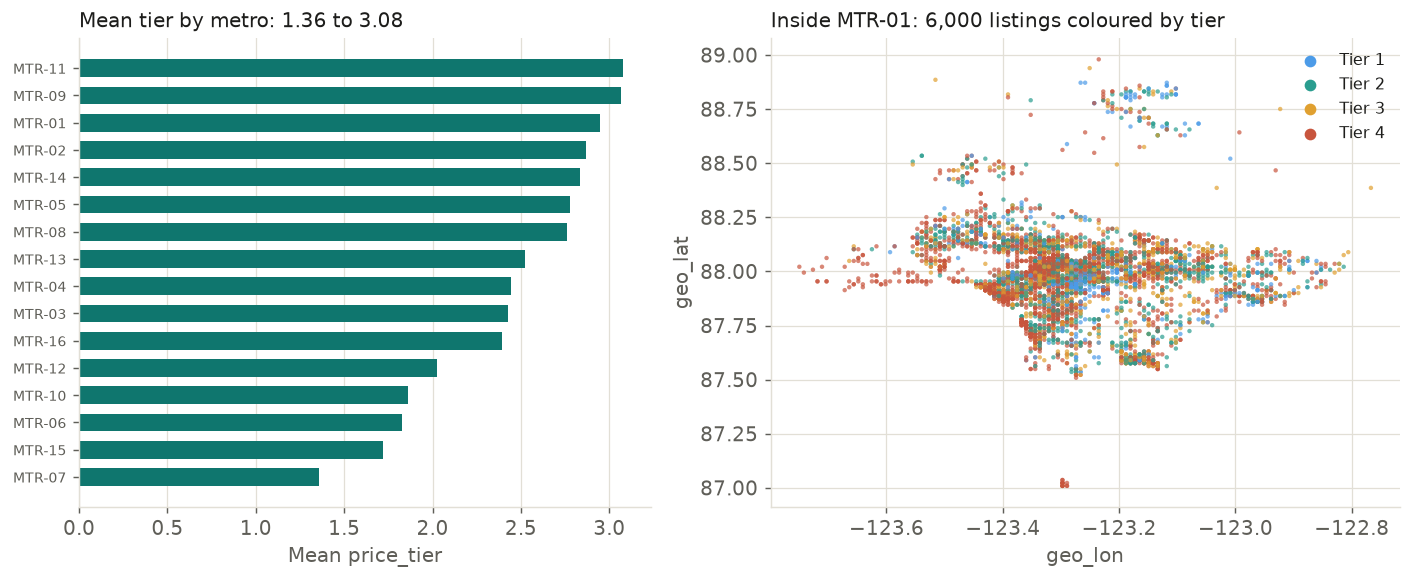
Geography: 16 metros
Preprocess without leaking
- Fit every learned step on training data only.
- Clean: 1,116 duplicates dropped, 62 invalid terms capped at 1,125 days.
- Linear baseline: macro F1 0.358 to 0.682 with preprocessing.
Features that moved the score
- IDs become counts: 34% of test listings have unseen operators.
- 145 facility flags: +0.004.
- Geometry of the coordinates: rotations, distances, k-means.
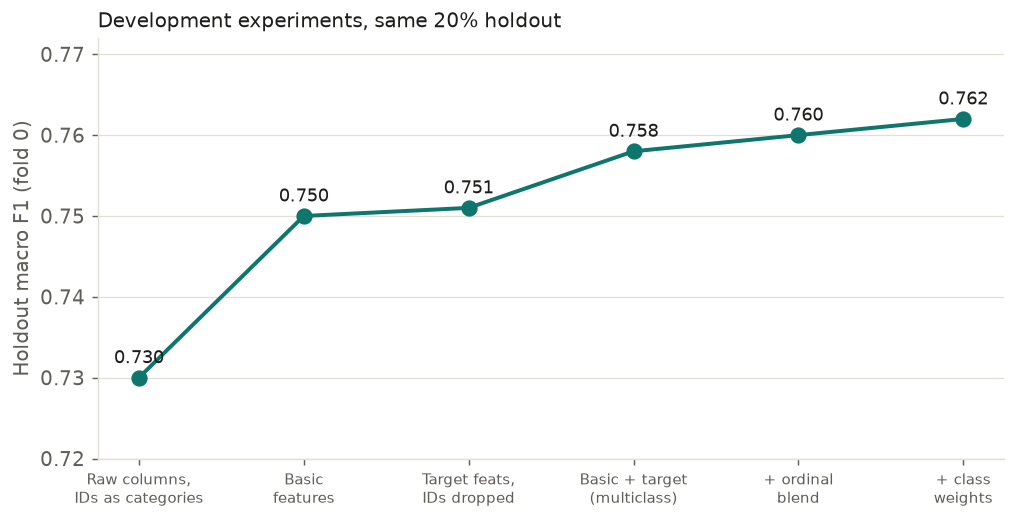
- Base 0.7303 to 0.7503 on the holdout.
Out-of-fold target encoding
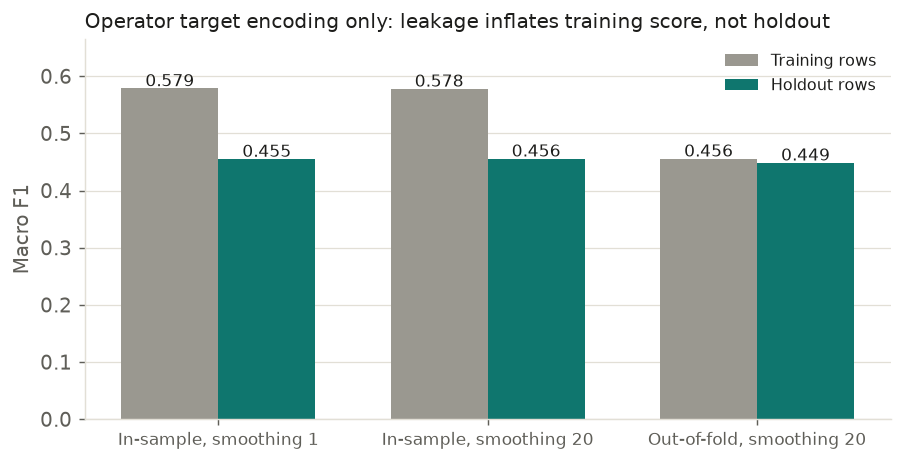
Smoothed tier share per group, m = 20, computed from the other four folds.
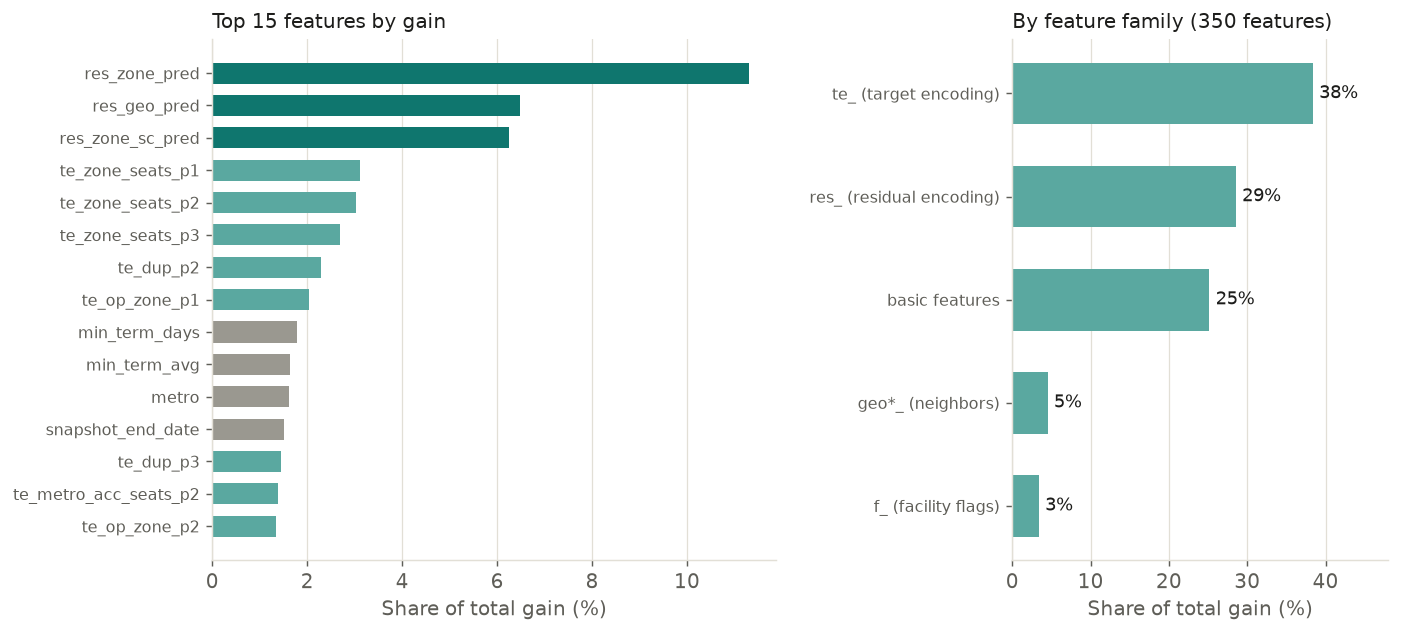
Residual encoding leads the importance chart
Models: from default to boosting
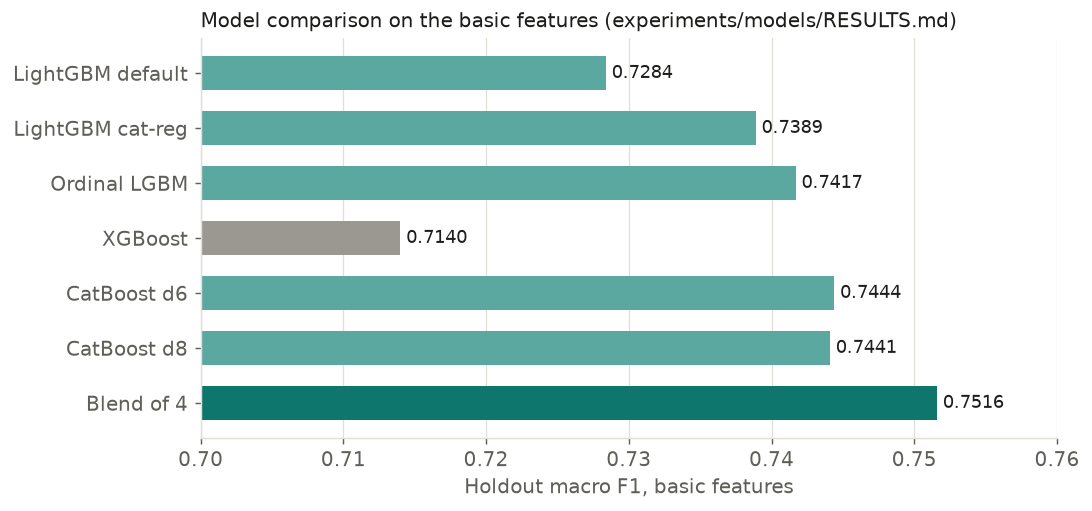
- Regularized LightGBM categoricals: +0.0105.
- Ordinal LightGBM: 0.7417. CatBoost: 0.7444. XGBoost: 0.7140.
Boosting, one round at a time
Validate with stratified 5-fold CV
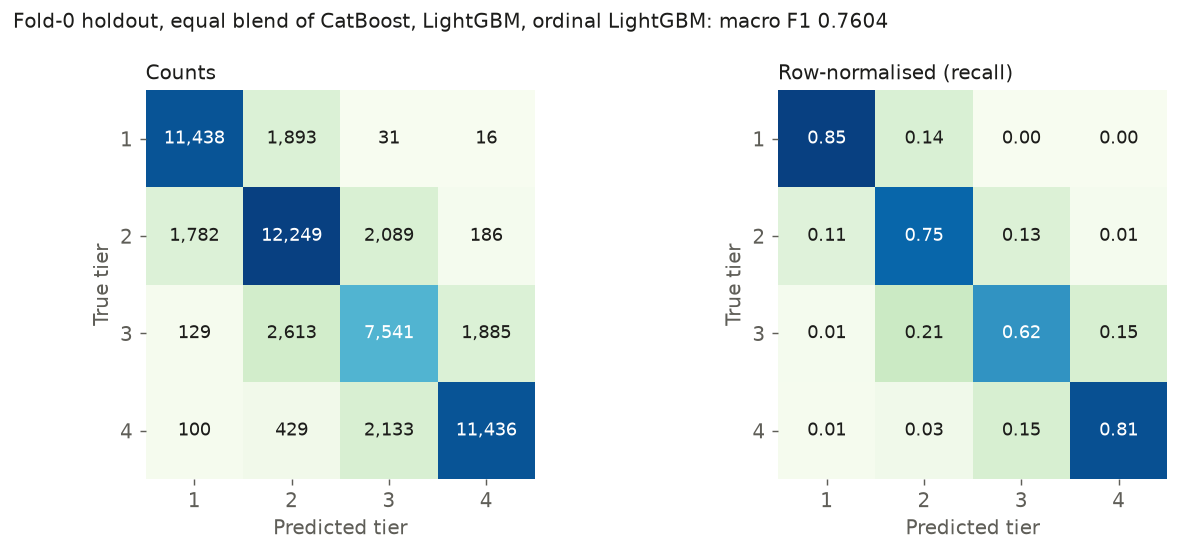
- Only 6.7% of errors are off by two tiers or more.
- Tier 3 is weakest: F1 0.629.
Blend, then weight the classes
| Stage | CV macro F1 |
|---|
| Multiclass LightGBM | 0.7520 |
| Ordinal LightGBM | 0.7547 |
| Blend | 0.7559 |
| Blend with class weights | 0.7577 |
Class weights [1, 0.98, 1.15, 0.852]. Honest gain: about +0.001.
Score progression
Lessons learned
- Handle high-cardinality IDs with care.
- Judge changes against noise (about 0.002).
- Blend models that make different errors.
- Unseen operators score about 0.03 lower.
Return to the section overview